从数据中心到桌面全面开放:英伟达以最高效率的Super VL和Bolt模型扩展Nemotron家族
Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Models
以下为原文逐段中文翻译,保留图表与说明。AI 翻译并经 AI 对照复核,仍可能存在错误;核对数据和引用时请同时查看原文。译文发布:2026年10月17日 06:30(北京时间)。
英伟达今日发布Nemotron 3.5 Super VL,这是一个开放的1200亿参数模型,为专业化的常驻智能体带来最快的任务完成速度和最高的准确性。
与它一同发布的还有两款新的边缘模型:Nemotron 3.5 Bolt 74B-A9B 24GB,针对本地智能体工作负载优化了每GB的智能与速度平衡;以及Nemotron 3.5 Bolt E4B 4GB,针对快速对话智能体优化了每GB的智能。
Super VL和Bolt 74B-A9B现已可用,Bolt E4B将于10月23日推出。这三款开放模型共同覆盖了从大型企业服务器到边缘设备和本地硬件的智能体部署全范围。
任何希望在英伟达基础设施上运行智能体的组织,现在都拥有了适合自身层级的开放、优化模型,无需在能力和可部署性之间做取舍。
Super VL和Bolt与Lightning和Ultra一同加入Nemotron家族。
8月发布的Lightning处理高吞吐量工作负载;Ultra处理最困难的推理任务;Bolt则将智能带到边缘。
Nemotron 3.5 Super VL:以五分之一规模达到前沿准确性
Super VL与Nemotron Coalition合作打造,在多模态智能体任务——指令遵循、工具使用、多步骤业务流程和视觉理解——上提供领先的准确性,其参数规模约为英伟达最大推理模型的五分之一,却与之不相上下。
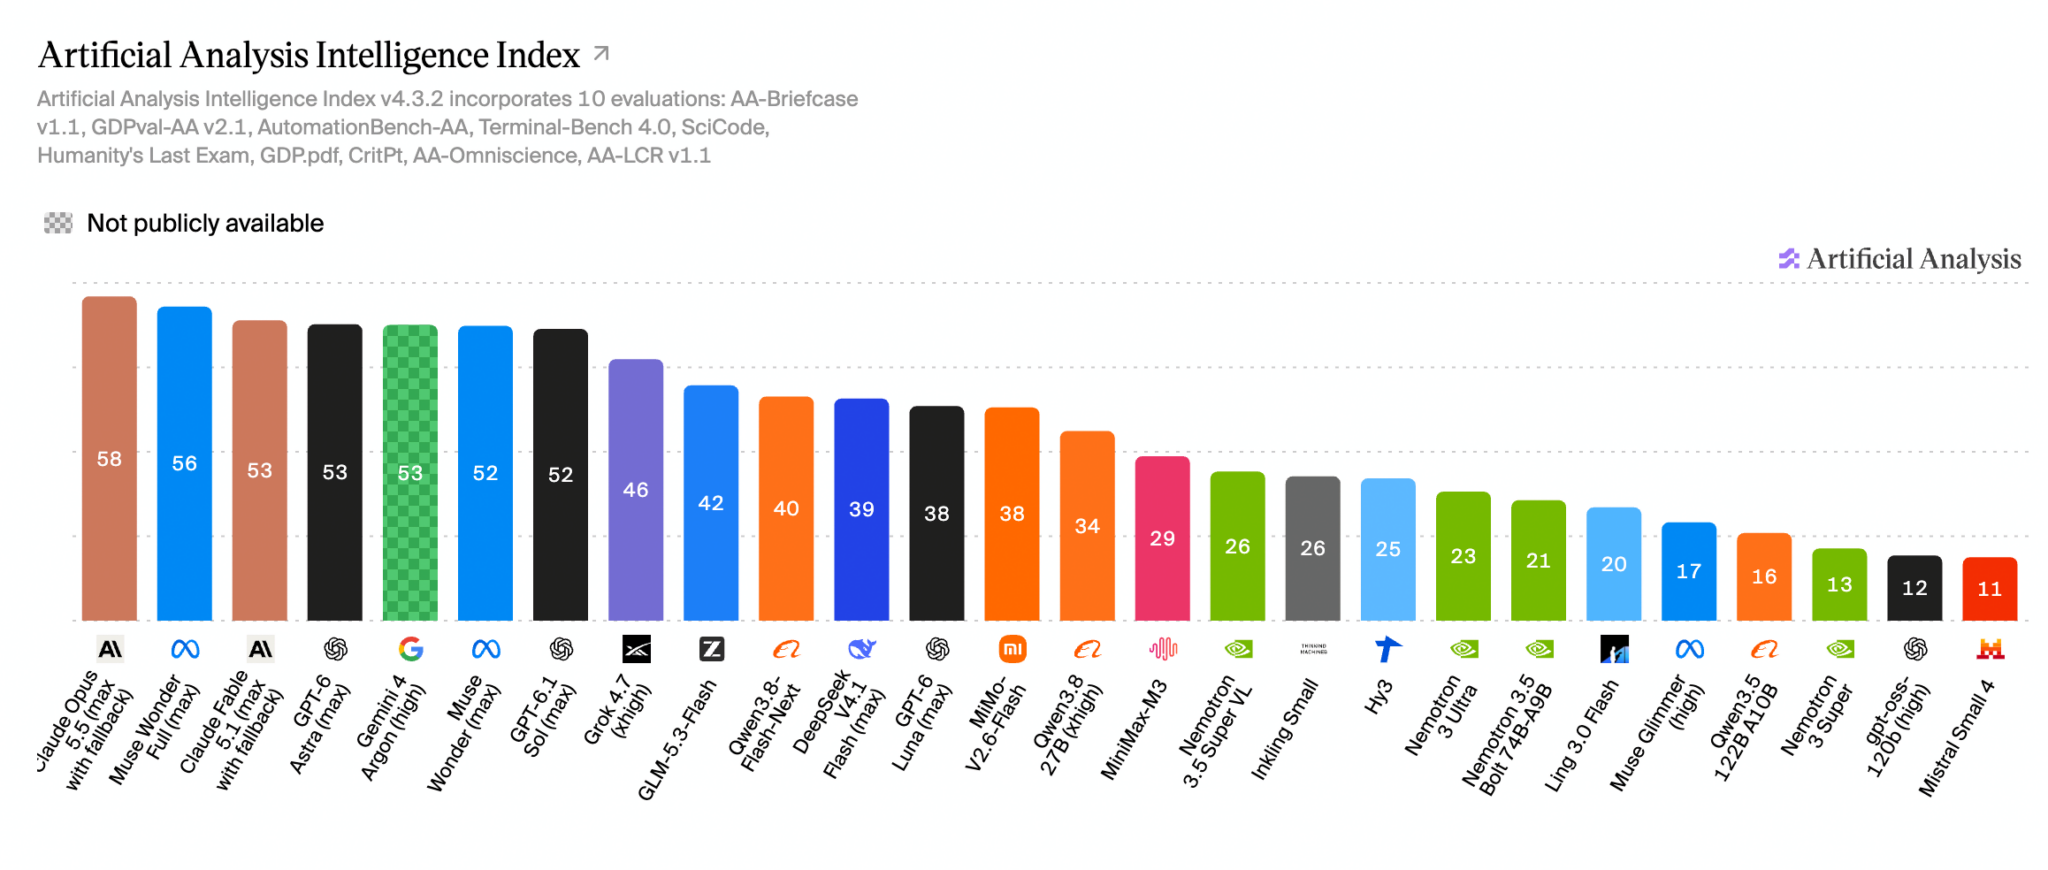
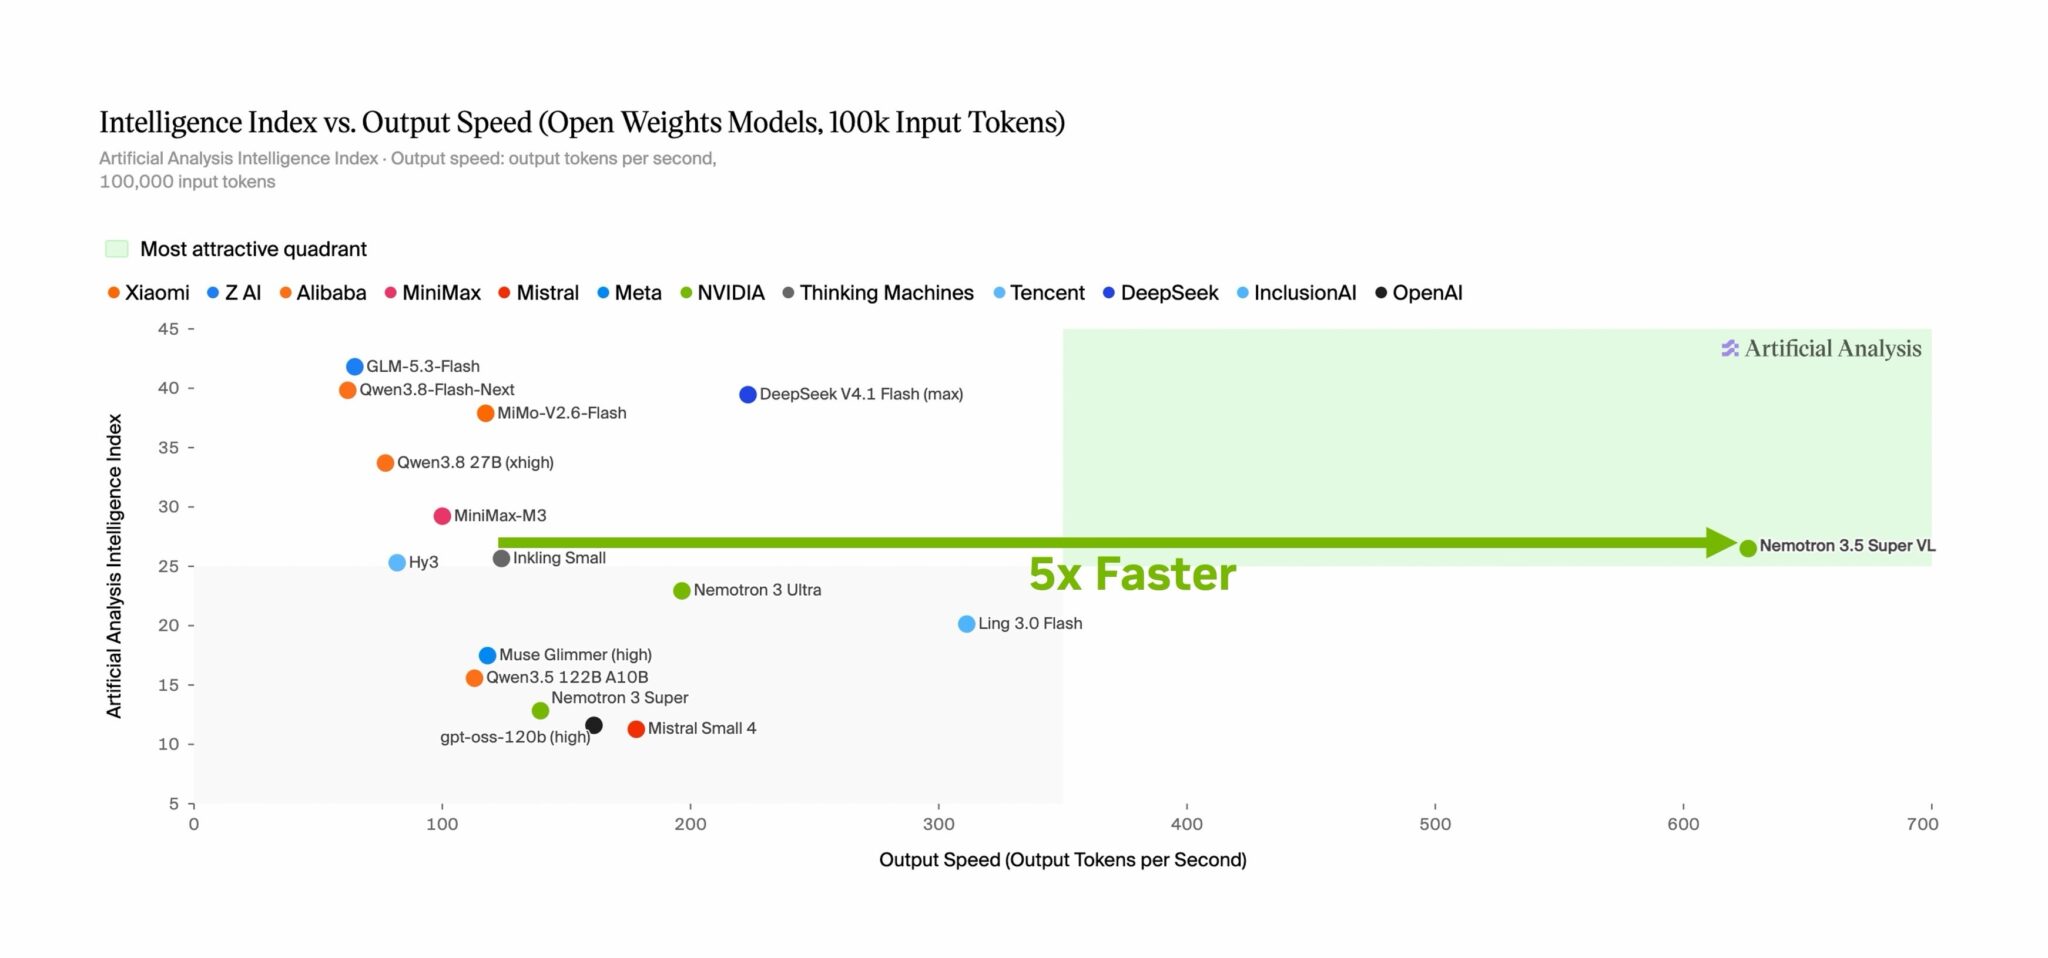
作为其同类中最快的开放智能体模型——比第二名快5倍——它帮助企业智能体在跨越数天或数周的工作流中更快地完成高吞吐量任务。
与闭源的前沿模型不同,组织可以在自己的数据上对Super VL进行后训练,将其部署在自己的基础设施上,并监管自己所构建的东西。
Nemotron 3.5 Bolt:边缘端的智能体智能
Bolt 74B-A9B 24GB旨在英伟达RTX/DGX Spark上本地运行日常智能体任务,采用原生2比特量化,以装入24GB内存并与其他应用程序同时运行。
相对于其他内存占用相近的模型,它在智能与速度之间提供了良好的平衡:足够聪明以完成大多数工作,却又比最聪明的模型快得多。
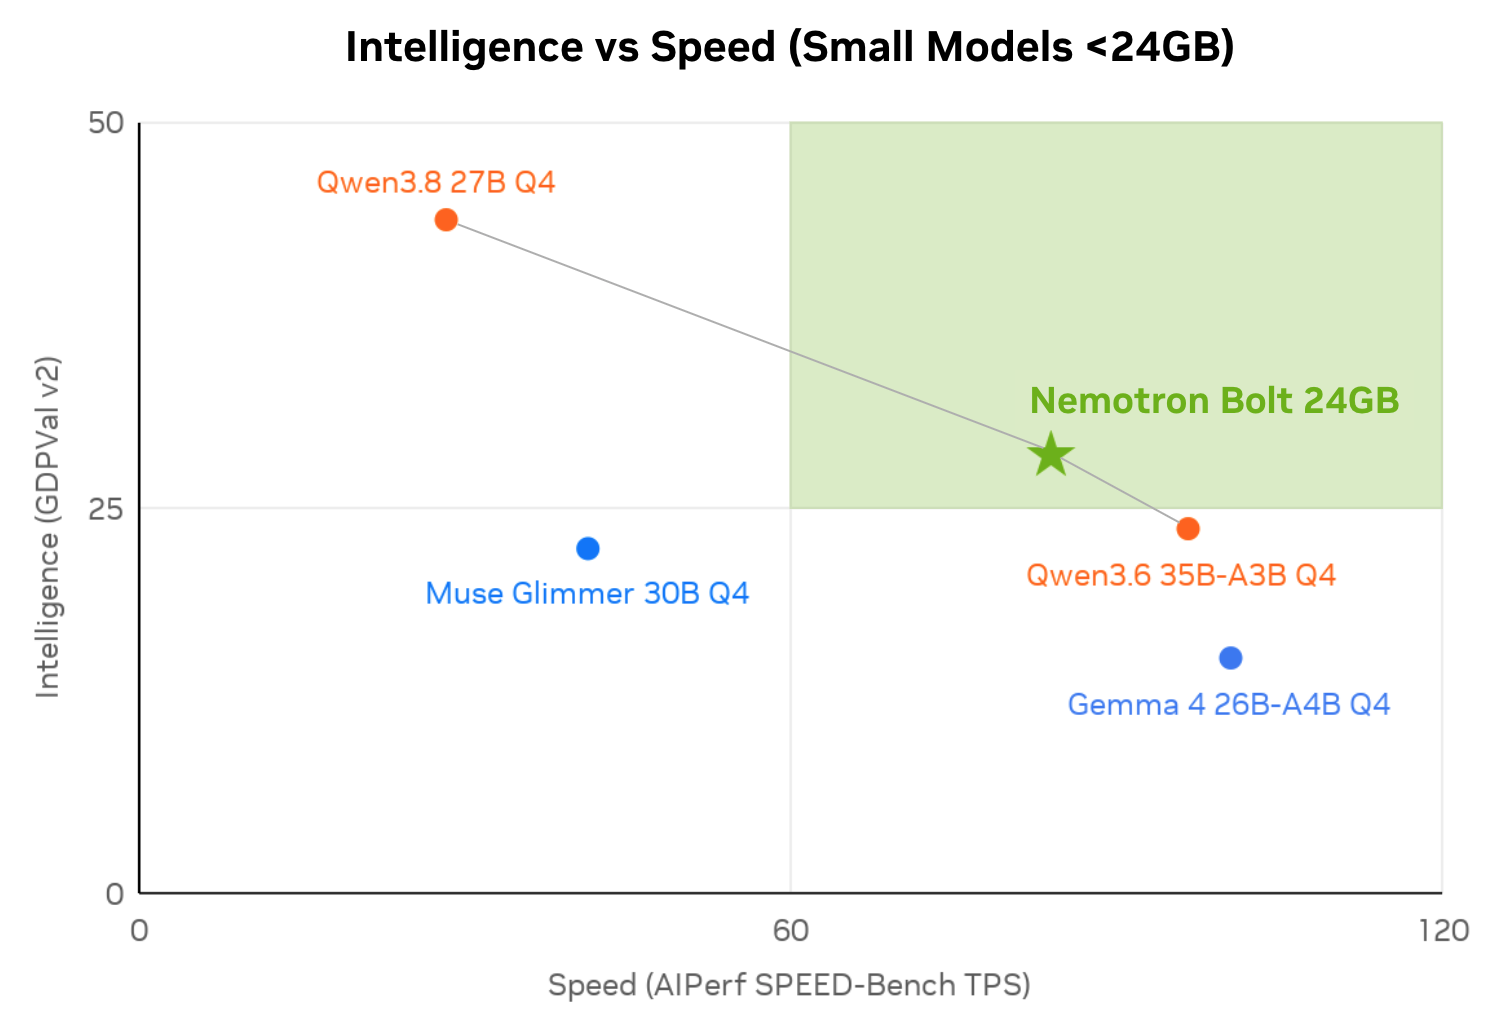
借助Bolt 74B-A9B 24GB,用户可以将项目委托给流行的本地智能体框架——从网络研究到编写和调试代码——全程无需将这些工作负载发送到云端。它是PinchBench上其同类中排名第一的开放模型,也是BrowseComp排名第二的开放模型。Bolt E4B 4GB为GeForce RTX、Jetson和RTX/DGX Spark上的实体和对话智能体而打造。它将自然对话与多轮智能体能力相结合,为快速的本地语音助手、交互式角色和嵌入式界面提供支持。
定制超级智能的采用
各行各业的数十个组织正在自己的数据、工具、政策和工作流上对Super VL进行后训练,以提高那些决定其智能体部署的专业任务的准确性。
各行各业的组织正在对Super VL进行后训练和定制。Scale AI为该模型进行后训练,用于Skydance的供应商信贷金融智能体和安永(EY)的并购尽职调查智能体。AfterQuery为Hebbia定制了该模型,用于信贷协议分析。AI21和Alice为该模型进行后训练,用于网络安全攻击韧性。Mercor在APEX-SWE编码基准上对该模型进行后训练,用于能够规划、编写和调试代码的编码智能体。ModelScope让开发者能够通过其ms-swift框架对该模型进行微调,用于专业化的多模态应用。
其他定制Nemotron 3.5 Super VL的组织包括:Ramp,用于金融文档智能;Dream,用于主权AI驱动的网络安全研究和漏洞分析;Lila Sciences,用于科学发现和搜索;以及R1,用于医疗理赔分析和收入周期管理。TrainLoop使用来自Nolla的皮肤病学数据对该模型进行后训练,Nolla刚刚成为首家获准使用AI开具初始患者处方的公司。集成Nemotron 3.5 Super VL的软件平台公司包括:
- Atlassian,用于跨Jira和Confluence等应用的智能体搜索等任务。
- CrowdStrike,正在为该模型进行定制,用于企业安全中的智能体蓝队防御。
- 达索系统(Dassault Systèmes),为工程设计和仿真提供支持。
- Perplexity,用于Perplexity Search和Computer中的搜索和智能体任务。
- Salesforce,正在定制Nemotron,以支持通过Missionforce Operations在安全的客户环境中将复杂的政府工作流数字化并自动化的AI智能体。
- 用于半导体设计验证的Synopsys软件可与该模型互操作。
Nemotron 3.5 Super VL实际看到了什么
Nemotron 3.5 Super VL的视觉语言优势针对智能体在实际中遇到的内容:光学字符识别、表格、图表以及视觉文档中的结构化信息。
它处理网页、提取文本、读取图形和图表,并从其发现的内容中返回洞察。这同样适用于PDF和智能体常处理的其他文档。
Nemotron 3.5 Super VL理解图像、网页和PDF,并据此采取行动。将文本和视觉理解结合在一个模型中,意味着智能体无需在独立系统之间路由任务——当工作从文档到数据再到决策时,上下文得以延续。
开放以实现最大程度的控制、安全和隐私
开放性和可定制性相辅相成。该模型附带开放权重、开放数据集和训练配方。
控制是双向的。组织可以在其安全和数据驻留要求所规定的地方运行该模型。他们还选择采用一个可以自行调整的模型,而不是受制于提供商限制的模型。
例如,在保险业,定制化的智能体可以反复扫描理赔以寻找欺诈标记。在金融服务领域,智能体可以审查信用评分,并根据组织自身的放贷标准标记相关活动。模型留在本地。数据保持私密。
定制通过NVIDIA NeMo、基于Python的流水线和开放数据集得到支持。
Nemotron 3.5 Super VL在预训练和持续预训练中使用了约26万亿个token进行训练,随后用约380万个样本以及跨数十个环境的强化学习进行后训练。
英伟达还在Hugging Face上发布开放数据集,涵盖智能体工具使用、金融、指令遵循、长上下文、公平性和视觉语言理解,以及NeMo Gym中的强化学习环境。
NVIDIA NIM将该模型打包为生产就绪的微服务,具有性能优化、经过验证的配置和企业级支持,每两周更新一次安全补丁和性能改进。
当模型运行在NVIDIA Dynamo上时,组织可以服务多达8倍的用户,同时延迟降低85%。
Nemotron 3.5 Super VL现已在Hugging Face、Open Router、ModelScope社区上提供,并以NVIDIA NIM的形式提供。
可在DGX Spark、DGX Station和RTX上运行
Nemotron 3.5 Super VL可在英伟达的全线硬件上运行:在DGX Spark、DGX Station、RTX PRO和RTX系统上实现桌面端的本地智能,在NVIDIA Jetson上实现边缘端,以及在数据中心和云环境中运行。
Nemotron 3.5 Bolt 74B-A9B 24GB现已在Hugging Face上提供,支持llama.cpp、Ollama、LM Studio、Unsloth和vLLM。它为10月16日上市的英伟达RTX Spark笔记本电脑而打造,也可在GeForce RTX PC、DGX Spark、DGX Station和RTX PRO工作站上运行。
下载开放权重,使用NVIDIA NeMo探索定制资源,或阅读技术博客以了解完整的架构解析。
通过订阅英伟达新闻、加入社区,并在LinkedIn、Instagram、X和Facebook上关注NVIDIA AI,及时了解智能体、NVIDIA Nemotron等更多信息。
探索自定进度的视频教程和直播。
请参阅有关软件产品信息的说明。
展开英文原文 · 与中文逐段对应
Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Models
NVIDIA today released Nemotron 3.5 Super VL, an open 120-billion-parameter model that delivers the fastest task completion and highest accuracy for specialized always-on agents.
Joining it are two new edge models: Nemotron 3.5 Bolt 74B-A9B 24GB, optimized to balance intelligence and speed per GB for local agentic workloads, and Nemotron 3.5 Bolt E4B 4GB, optimized for intelligence per GB for fast conversational agents.
Super VL and Bolt 74B-A9B are available now, with Bolt E4B coming Oct. 23. The three open models together cover the full range of agent deployments, from large enterprise servers down to edge devices and local hardware.
Any organization that wants to run agents on NVIDIA infrastructure now has an open, optimized model for their tier, without having to choose between capability and deployability.
Super VL and Bolt join the Nemotron family alongside Lightning and Ultra.
Lightning, released in August, handles high-throughput workloads; Ultra handles the hardest reasoning tasks; and Bolt brings intelligence to the edge.
Nemotron 3.5 Super VL: Frontier Accuracy at One-Fifth the Size
Super VL, built in collaboration with the Nemotron Coalition , delivers leading accuracy on multimodal agentic tasks — instruction following, tool use, multistep business workflows, and visual understanding — comparable with NVIDIA’s largest reasoning model at roughly one-fifth the parameter count.
As the fastest open agentic model in its class — 5x faster than the next best — it helps enterprise agents complete high-volume tasks faster across workflows that span days or weeks.
Unlike closed frontier models, organizations can post-train Super VL on their own data, deploy it on their own infrastructure and oversee what they build.
Nemotron 3.5 Bolt: Agentic Intelligence at the Edge
Bolt 74B-A9B 24GB is designed to run everyday agentic tasks locally on NVIDIA RTX/DGX Spark, using a native 2-bit quantization to fit in 24GB of memory and run alongside other applications.
Relative to other models with a similar memory footprint, it provides a good balance of intelligence and speed: smart enough to get most jobs done, yet much faster than the smartest models.
With Bolt 74B-A9B 24GB, users can delegate their projects to popular local agent harnesses — from researching the web to writing to debugging code — all without sending those workloads to the cloud. It is the #1 open model in its class on PinchBench , and the #2 open model for BrowseComp . Bolt E4B 4GB is built for physical and conversational agents on GeForce RTX, Jetson, and RTX/DGX Spark. It combines natural conversation with multi-turn agentic capabilities to power fast local voice assistants, interactive characters and embedded interfaces.
Adoption of Custom Super Intelligence
Dozens of organizations across industries are post-training Super VL on their own data, tools, policies and workflows to push accuracy higher on the specialized tasks that define their agent deployments.
Super VL is being post-trained and customized by organizations across industries. Scale AI post-trained the model for Skydance’s vendor credit finance agent and for EY’s M&A due diligence agent. AfterQuery customized the model for Hebbia for credit agreement analysis. AI21 and Alice post-trained the model for cybersecurity attack resilience. Mercor post-trained the model on APEX-SWE coding benchmark, for coding agents that plan, write and debug code. ModelScope enables developers to fine-tune the model through its ms-swift framework for specialized multimodal applications.
Additional organizations customizing Nemotron 3.5 Super VL include Ramp for financial document intelligence; Dream , sovereign AI-powered cybersecurity research and vulnerability analysis; Lila Sciences for scientific discovery and search, and R1 for medical claims analysis and revenue cycle management. TrainLoop post-trained the model with dermatology data from Nolla, which just became the first company approved for AI to write initial patient prescriptions. Software platform companies integrating Nemotron 3.5 Super VL include:
- Atlassian, for tasks like agentic search across apps such as Jira and Confluence.
- CrowdStrike, which is customizing the model for agentic blue teaming in enterprise security.
- Dassault Systèmes, powering engineering design and simulation.
- Perplexity, for search and agentic tasks in Perplexity Search and Computer.
- Salesforce, which is customizing Nemotron to power AI agents that digitize and automate complex government workflows in secure customer environments through Missionforce Operations.
- Synopsys software for semiconductor design verification interoperates with the model.
What Nemotron 3.5 Super VL Actually Sees
Nemotron 3.5 Super VL’s vision language strengths are targeted at what agents encounter in practice: optical character recognition, tables, charts and structured information in visual documents.
It processes a web page, extracts text, reads graphs and charts, and returns insights from what it finds. The same applies to PDFs and other documents agents commonly work with.
Nemotron 3.5 Super VL understands images, webpages and PDFs and acts on that understanding. Combining text and visual understanding in one model means agents don’t need to route tasks between separate systems — context carries through as work moves from document to data to decision.
Open for Maximum Control, Security, and Privacy
Openness and customizability reinforce each other. The model ships with open weights, open datasets and training recipes.
Control runs in two directions. Organizations can run the model wherever their security and data-residency requirements dictate. They also choose to adopt a model they can adapt, rather than one subject to a provider’s restrictions.
In insurance, for example, a customized agent can scan claims for fraud markers on repeat. In financial services, an agent can review credit scores and flag activity against an organization’s own lending criteria. The model stays on premises. The data stays private.
Customization is supported through NVIDIA NeMo, Python-based pipelines and open datasets.
Nemotron 3.5 Super VL was trained on about 26 trillion tokens across pretraining and continued pretraining, then post-trained with roughly 3.8 million samples and reinforcement learning across dozens of environments.
NVIDIA is also releasing open datasets on Hugging Face spanning agentic tool use , finance, instruction following, long context, fairness and vision-language understanding, along with the reinforcement learning environments in NeMo Gym.
NVIDIA NIM packages the model as a production-ready microservice with performance-optimized, validated configurations and enterprise-grade support, refreshed every two weeks with security patches and performance improvements.
And with the model running on NVIDIA Dynamo, organizations can serve up to 8x more users with 85% lower latency.
Nemotron 3.5 Super VL is available now on Hugging Face, Open Router, ModelScope community and as NVIDIA NIM.
Runs on DGX Spark, DGX Station, and RTX
Nemotron 3.5 Super VL runs across NVIDIA’s full hardware stack: on DGX Spark , DGX Station , RTX PRO and RTX systems for local intelligence at the desktop, on NVIDIA Jetson at the edge, and across data center and cloud environments.
Nemotron 3.5 Bolt 74B-A9B 24GB is available now on Hugging Face, with support for llama.cpp, Ollama, LM Studio, Unsloth, and vLLM. Built for NVIDIA RTX Spark laptops arriving Oct. 16, it also runs on GeForce RTX PCs , DGX Spark , DGX Station and RTX PRO workstations .
Download the open weights , explore customization resources with NVIDIA NeMo, or read the technical blog for the full architecture breakdown.
Stay up to date on agents, NVIDIA Nemotron and more by subscribing to NVIDIA news , joining the community , and following NVIDIA AI on LinkedIn , Instagram , X and Facebook .
Explore self-paced video tutorials and livestreams .
See notice regarding software product information.
查看本期独立摘要
中文独立摘要 · AI 整理
这件事
据英伟达官方博客报道,英伟达发布Nemotron 3.5 Super VL,这是一个开放权重、拥有1200亿参数的模型,为专用的常驻智能体带来最快的任务完成速度与最高准确率。同时发布两款新的边缘模型:Nemotron 3.5 Bolt 74B-A9B 24GB,针对本地智能体工作负载优化智能与每GB速度的平衡;以及Nemotron 3.5 Bolt E4B 4GB,针对快速对话式智能体优化每GB智能。Super VL与Bolt 74B-A9B现已可用,Bolt E4B将于10月23日发布。三款开放模型覆盖从大型企业服务器到边缘设备及本地硬件的各类智能体部署。
本页概括所列来源的重点,属于独立摘要;完整报道请阅读原站。整理时间:2026年10月17日 04:44(北京时间)。
信息从哪里来
依据 NVIDIA 官方博客 的RSS 摘要与原文节选整理,事实核对限于列明材料;不是原文全文翻译。
- NVIDIA 官方博客 来源报道(RSS 摘要与原文节选)